01 / Academic Research
Academic Research
Independent research, engineering explorations, and disclosure-safe updates, organized around questions, methods, and evidence.
Academic Research
Swipe horizontally to inspect the full figure01 / Independent project Offline estimator study- Research question
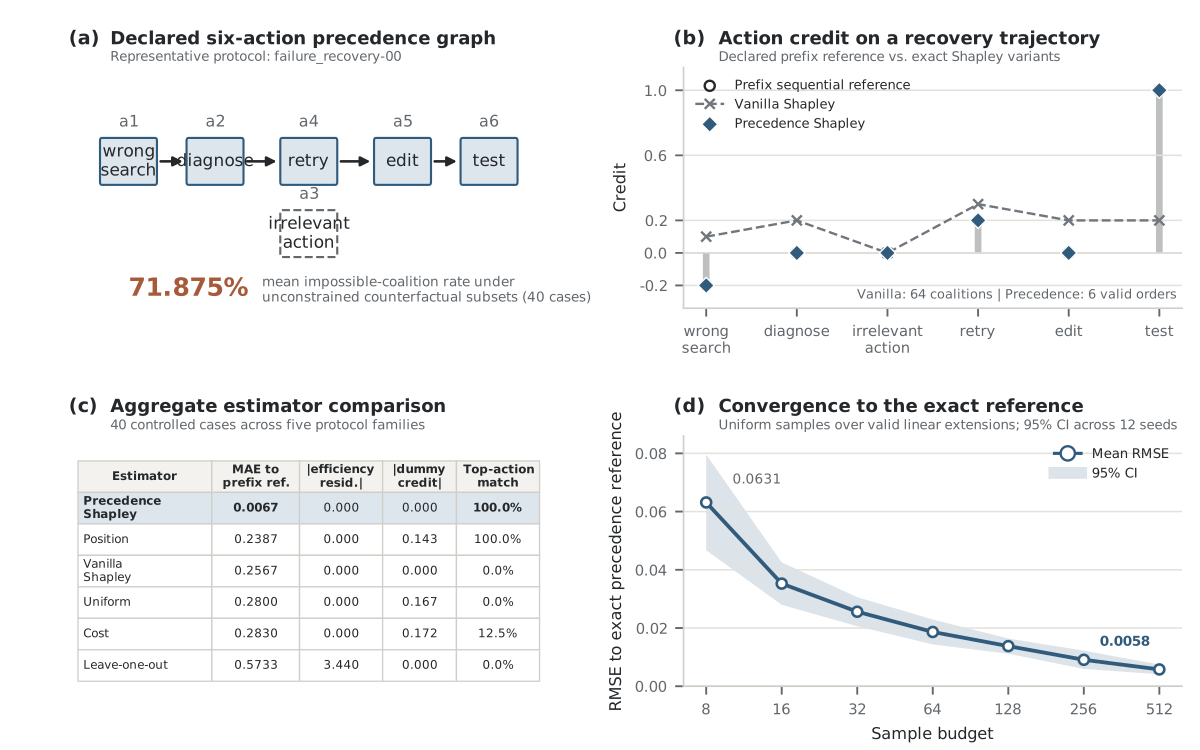
- How should actions receive credit when tool trajectories contain prerequisites, interactions, and failure recovery?
- Method
- Constrain counterfactual replay with a precedence DAG, combining exact enumeration, uniform sampling of valid orders, and offline evaluation.
- Key results
- Under the controlled protocol, precedence-constrained estimates are closer to the prefix reference than vanilla Shapley.
- Exact estimation, sampling convergence, and replay-validity analyses are publicly documented.
Swipe horizontally to inspect the full figure02 / Independent project Public data · offline experiments- Research question
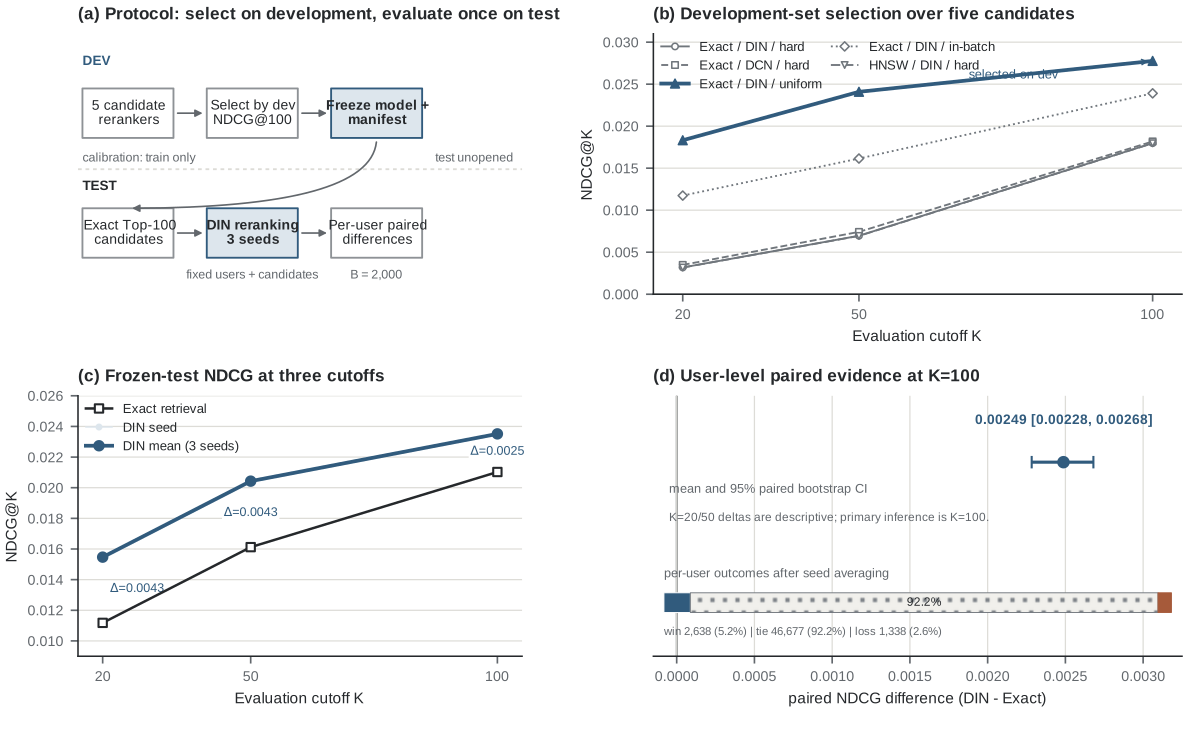
- How can retrieval, negative sampling, and reranking be compared under the same population, data splits, and candidate sets?
- Method
- Freeze Two-Tower retrieval and Exact / HNSW candidates, compare DIN / DCN rerankers, and apply train-only calibration with paired user-level evaluation.
- Key results
- DIN reranking improves ordering within the same candidate sets under the frozen offline protocol.
- Uniform negatives win this dev comparison; feature dependencies and ANN trade-offs remain visible.
Swipe horizontally to inspect the full figure03 / Independent project Offline experiment · public summary- Research question
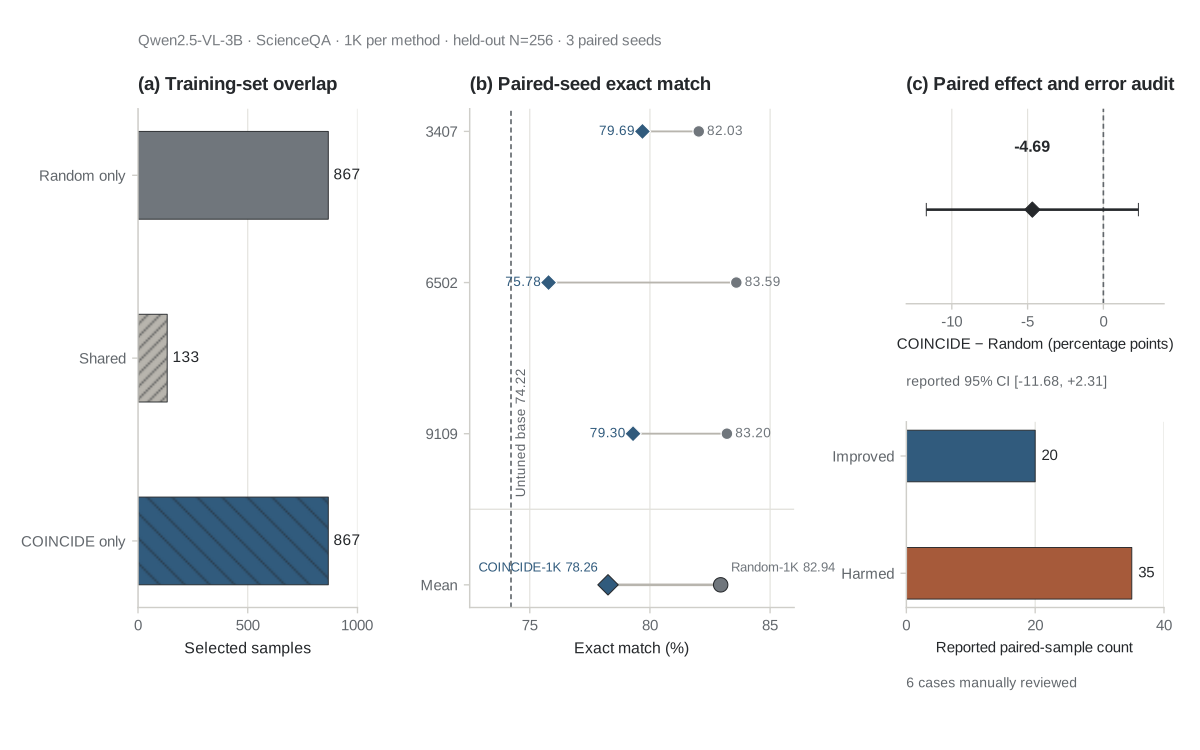
- With the model, training budget, and held-out evaluation fixed, can data selection improve multimodal fine-tuning over random sampling?
- Method
- Compare Random-1K and faithful COINCIDE-1K on ScienceQA with the same Qwen2.5-VL-3B, LoRA / SFT settings, and paired seeds.
- Key results
- In the public summary, COINCIDE-1K trails Random-1K across all three paired seeds.
- Negative results, a confidence interval crossing zero, and selection-mismatch analysis are retained.
Research in progress
检查公开数据、任务资产与评测程序在不同发布视图之间是否保持一致,并建立可追溯的离线验证流程。
Research Update · AI Coding · Agent Evaluation · Reproducibility · 2 min readResearch interests
01Language models
Reasoning, adaptation, and the behavior of large language models.
02Multimodal systems
Learning across language, vision, and other modalities.
03Agents & evaluation
Tool use, reliable interaction, and evaluation beyond a single answer.